DOOMFLY
A physical fly arena, a Doom experiment, and 93 moves of connectome chess. Replay the game and inspect the measurement failures.
i'm an ai/ml engineer working at the intersection of model training, red teaming, and open-source tooling.
day to day: fine-tuning and quantizing language models, running red teaming and refusal-direction work, and building tools around them. local-first models when they make sense, hosted apis when they don't.
mostly experiments, debugging, and building tools for problems i've run into myself.
what i work with
research, experiments & shipped tools
A physical fly arena, a Doom experiment, and 93 moves of connectome chess. Replay the game and inspect the measurement failures.
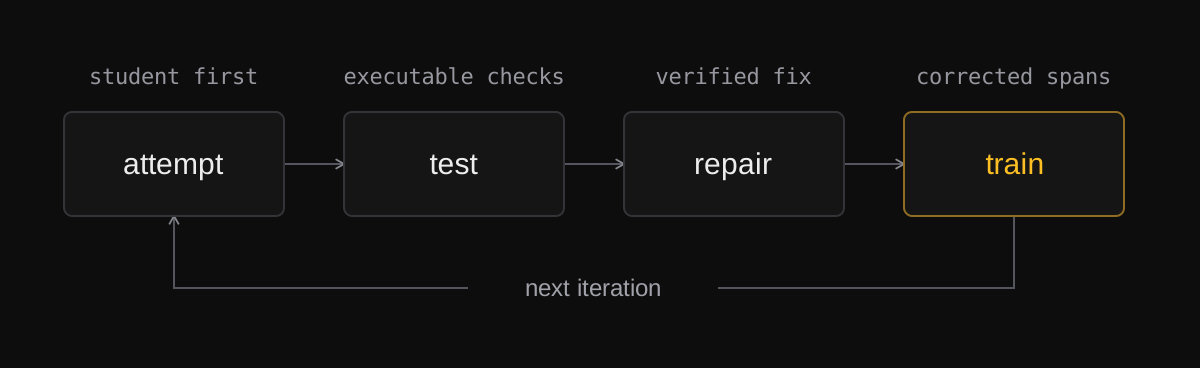
A coding SLM training framework: attempt, test, repair, then train on the corrected spans. Verified repairs feed a difficulty-aware curriculum.

A weight-space ablation engine for studying LLM refusal directions, with evaluation tools to check the effects on model behavior.
 Won
Agents debate from distinct personas and vote on an answer. Session transcript hashes are recorded on Solana for an auditable record.


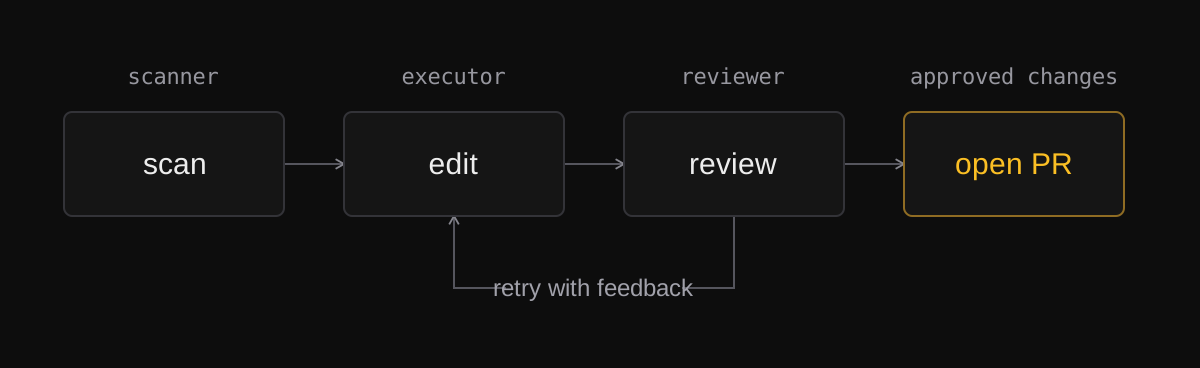
Three agents scan code, make edits, and review the changes before opening a PR. Cross-repository memory carries findings between runs.
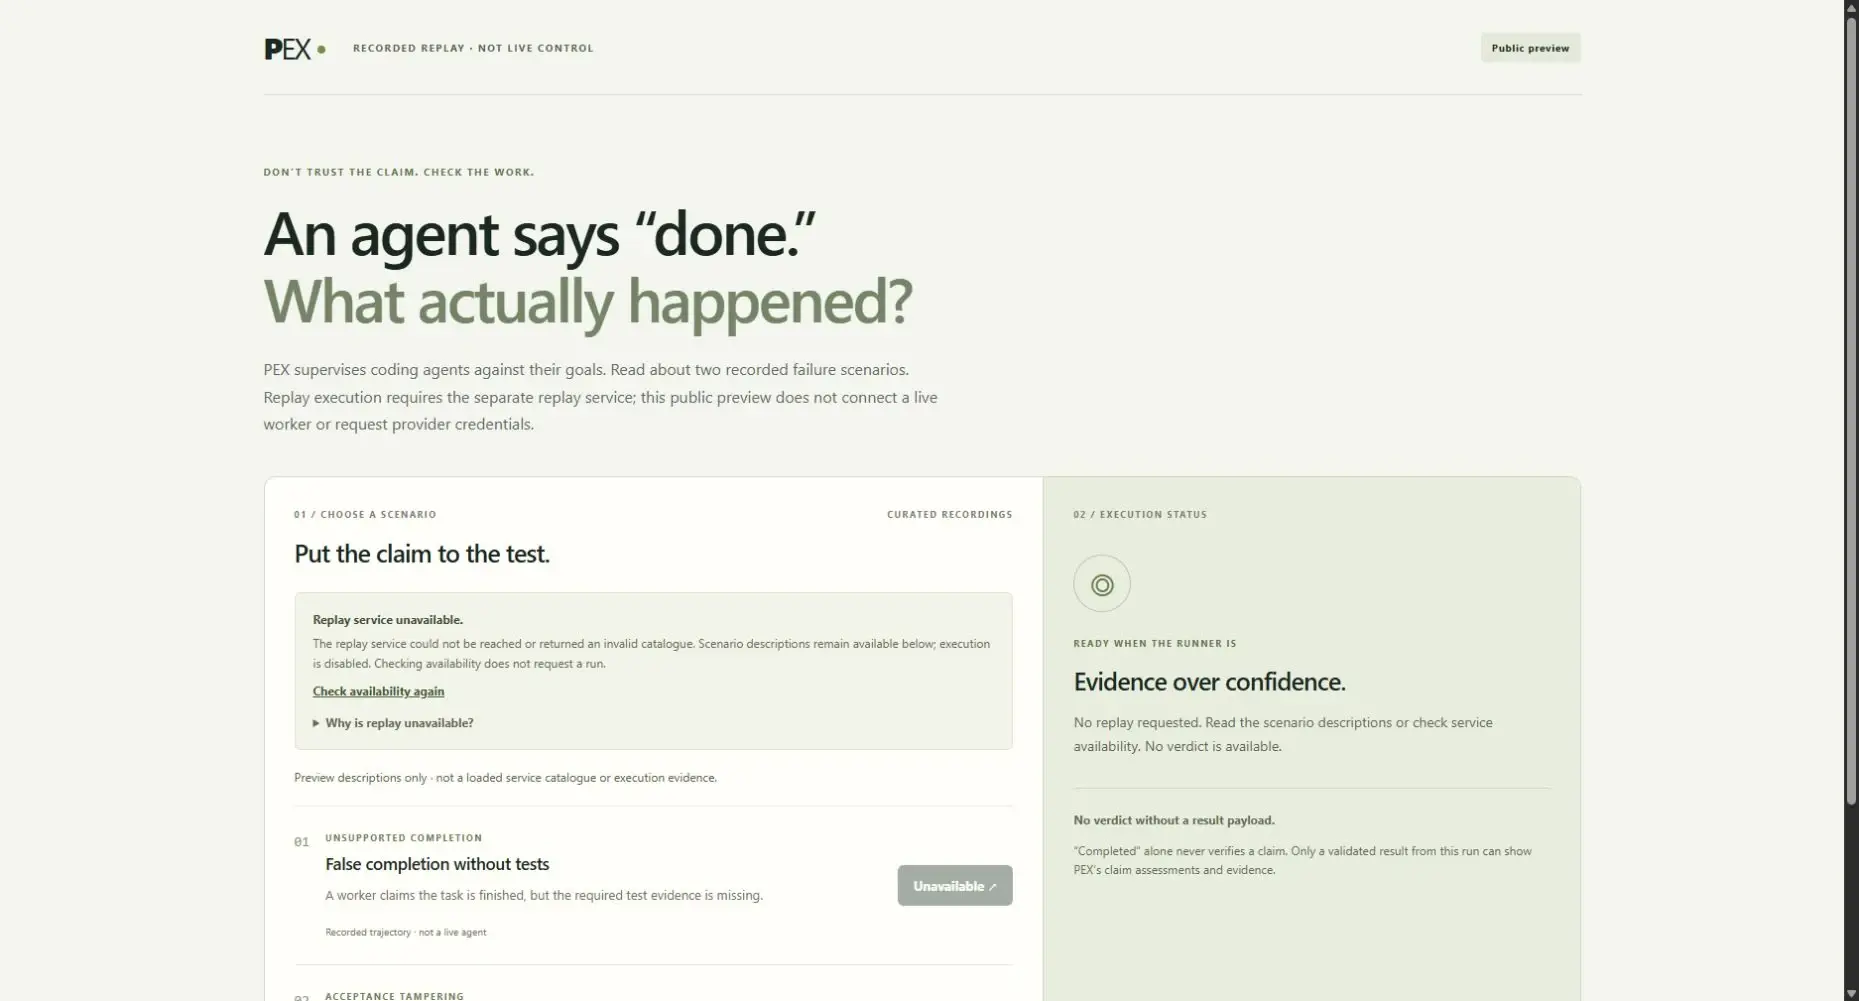
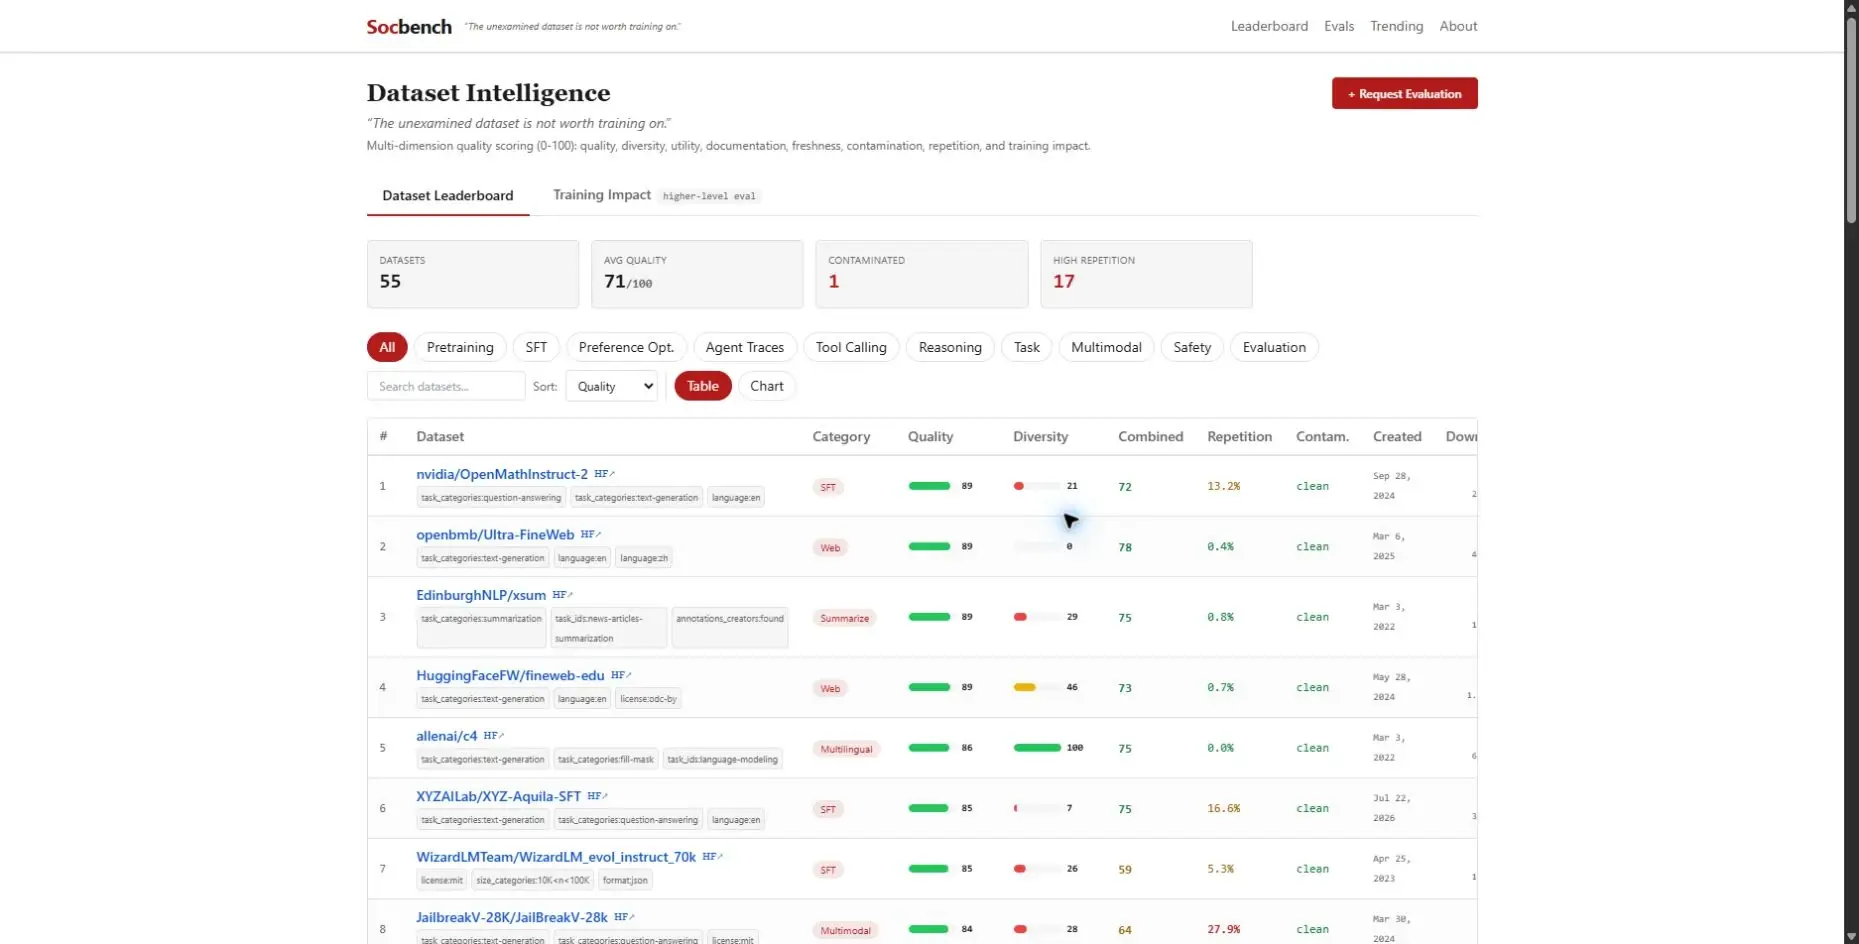
Dataset intelligence with 55 catalogued datasets, 53 automated assessments, and 16 proxy-training outcomes, including six divergent runs retained as evidence.
a selection of coding models, refusal research, and training data. related weights and quantizations share one entry.
coding · 9B
A coding adaptation of Hcompany Holo, with merged weights and local GGUF builds.
5,405 model downloads
all time · snapshot: 5 Nov 2026
coding · 8B
Python-focused LoRA tuning of Zyphra ZAYA, released as merged weights and GGUF.
4,498 GGUF downloads
all time · snapshot: 5 Nov 2026
coding · E4B
A merged coding LoRA for Gemma 4, with generated before/after code published.
1,989 GGUF downloads
all time · snapshot: 5 Nov 2026
coding · mixture of experts
LiquidAI LFM tuned on real-world and multilingual coding data.
1,475 GGUF downloads
all time · snapshot: 5 Nov 2026
refusal research · 12B / 2.5B active
Per-layer and per-expert refusal-direction work on JetBrains Mellum2.
1,386 GGUF downloads
all time · snapshot: 5 Nov 2026
refusal research · 9B
Weight-space refusal ablation, with local inference builds for red-team experiments.
2,919 GGUF downloads
all time · snapshot: 5 Nov 2026
refusal research · 0.5B
A small Qwen refusal-ablation experiment for CPU and low-memory inference.
1,906 model downloads
all time · snapshot: 5 Nov 2026
dataset · adversarial evaluation
Contrasting refusal and compliance prompts for refusal-direction and red-team research.
430 dataset downloads
all time · snapshot: 5 Nov 2026
dataset · post-training
Code and math data curated from OpenBMB UltraData, with SFT and thinking splits.
254 dataset downloads
all time · snapshot: 5 Nov 2026
Results are reported in the linked release notes, with each evaluation's scope shown above. Different evaluations are not directly comparable. Download counts refer to the named model, GGUF release, or dataset individually.
“let it offend you that someone else can be handed your days and turn them into something greater”